How this tool works
HTML Text to PDF: a practical guide
Reads a selected HTML file as an inert document, removes active elements and exports its text. It does not execute the HTML or fetch a website.
Steps to use this tool
- Select a local HTML file.
- Choose HTML Text to PDF.
- Review the exported text rather than expecting a webpage screenshot.
Tested example — 19 October 2026
The sample preserves Visible actual words and excludes SECRET_SCRIPT from the source script element.
Selected sample: local.html (121 bytes).
Measured output: local.pdf — 6245 bytes; 1 PDF pages.
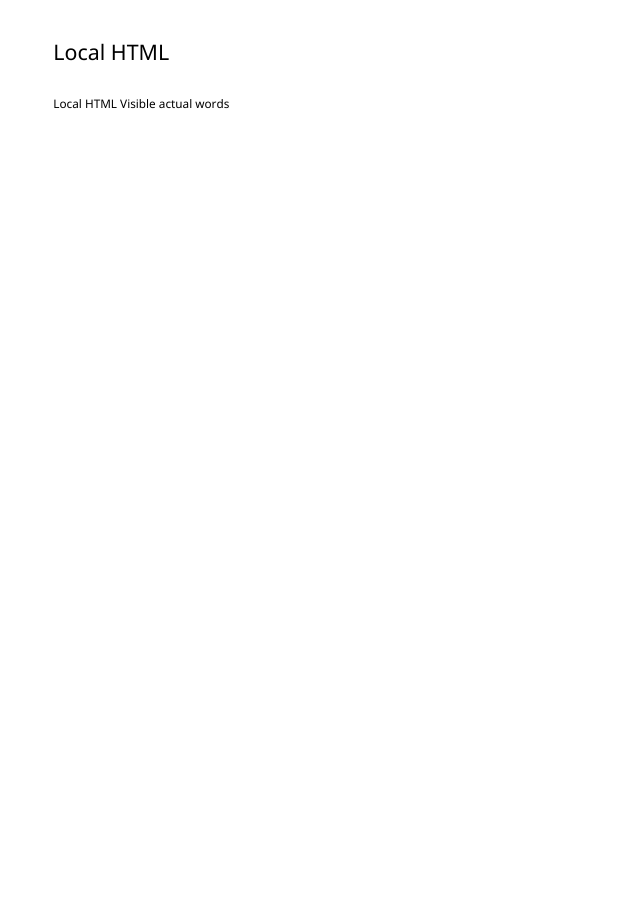
Test environment: Node + native canvas + actual site-ui.js form integration in LinkeDOM Representative sample; inspect your own output.
Check the result
Search the PDF for a known paragraph from the HTML. Confirm that script contents have not appeared as document text.
Files and privacy
The public tool processes selected documents in your browser. It does not send document bytes to a conversion server. The page and its bundled libraries still download from this website. Keep the original, use an up-to-date browser and inspect your output before sharing it. See the privacy policy for hosting and support information.
If processing fails
Entering a website URL does not request a screenshot service here. Use the browser's Print to PDF command when you need the rendered page and its CSS layout.
Implementation notes and sample evidence updated 2026-10-19. These notes describe the supported operation and its limits.
Check the local-processing claim in your browser’s Network panel.